Same Model. Same Cost. Different Answers.
The real AI advantage is not the model you pick. It is how your knowledge is organized so an agent can find the right pieces.
Two parents, same request: only one of them got the job done.
Lucy and Matt are parents of the same boy. On a Saturday afternoon at home, they sit down to sort out his volleyball subscription.
Same son, same AI assistant, same top-tier model behind it. Each types the same request: "Help me sign our son up for volleyball."
Matt types the request cold, with nothing else attached. The assistant knows nothing about this family and hands back a polite checklist:
- Fill in the registration form
- Bring a medical certificate
- Check your insurance
Everything in it is true, and none of it gets the job done.
Lucy's assistant, connected to the family knowledge Lucy keeps organized, hands back a registration form already filled in, a note that this season's insurance covers competition play, and a payment ready to approve.
Same model. Same cost. Different answers.
Nothing about the machine explains the gap. What explains it is what sat behind the question: the real advantage is not the model you pick, it is how your knowledge is organized so an agent can find the right pieces.
The model stops being the differentiator sooner than you think
When people talk about AI, they talk about models. Which one is newest, which one tops the benchmark, which one is cheaper per million tokens...
A weak model will fail you, of course. But once a model is good enough for your task, the next gain rarely comes from swapping it for a slightly better one. It comes from something far less glamorous: what the model knows about your situation.
A large language model (LLM) knows an enormous amount about the world.
It knows nothing about your world: your contracts, your constraints, your past decisions and the reasons behind them. An AI agent, meaning an LLM that can look things up and take actions on your behalf, is only as useful as the knowledge it can reach.
So the question is not "which model should we buy?" It is a humbler and much harder one: how does the model get to know our use case, reliably, every time?
Your AI service cannot know the information you did not provide
That is a question about how you organize what you know: the model brings the intelligence, your knowledge brings the context.
Consolidating is not organizing
Start with where useful knowledge actually lives. Some of it sits in software-as-a-service tools. Some in a wiki that nobody has touched in a year. Some in online storage, some in email threads, and a surprising amount, still, on paper in a drawer.
The first instinct is sensible: consolidate. Bring it together, logically if not physically, so that one place knows where everything is.
Then comes the second instinct, and it is the trap. We feel the job is done once everything sits in the same folder.
It is not. A flat folder holding thousands of files has moved the problem, not solved it. Whoever asks a question, you or the agent, still has to scan the whole thing, document by document, to decide what matters right now.
The question was "how much can I feed the model?" The better question is "how does the agent pick the right pieces?"
The problem is selection, not storage.
Boxes, drawers and labels
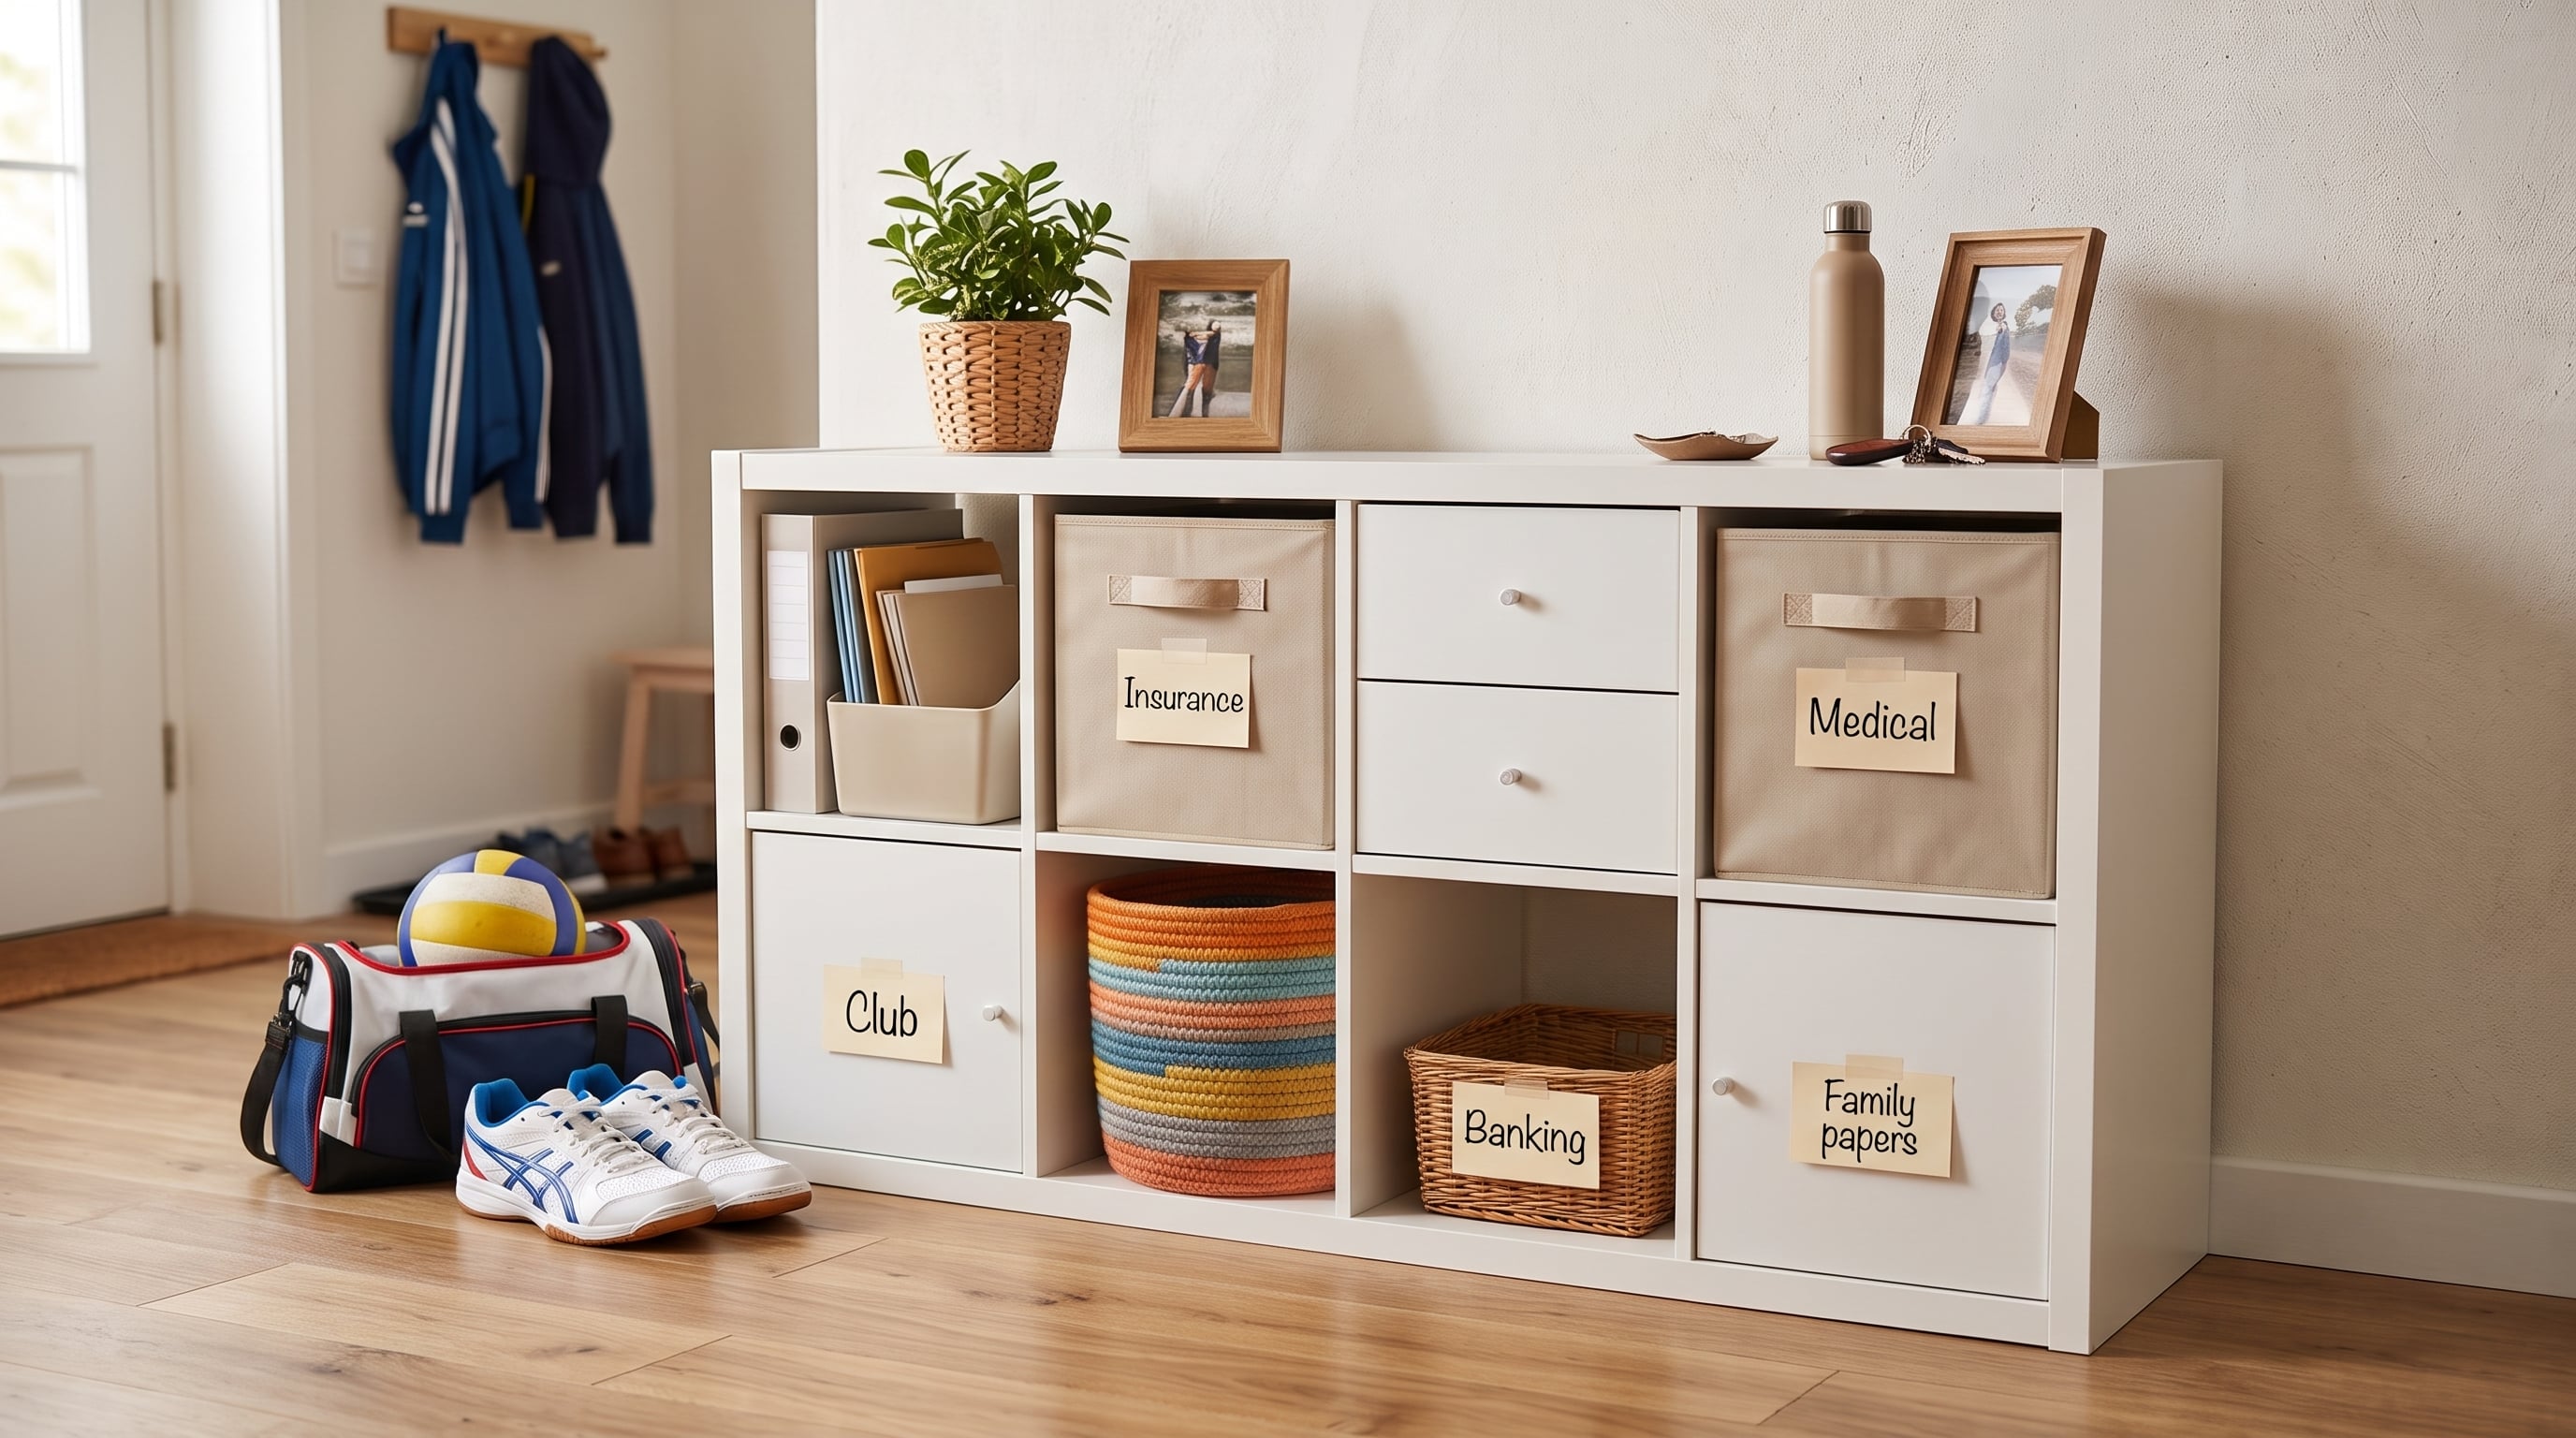
To make selection concrete, picture a KALLAX-style cube shelf (the famous IKEA shelf: a grid of boxes you can fill with anything). A few cubes hold people contact details, one holds contracts, one holds ongoing projects.
The agent no longer has to read the whole room. It only needs to know which box to open.
The real design work happens inside the cube. A cube can take a drawer, a door, a basket, or stay empty. In other words, you choose the granularity of the knowledge you store, and that choice shapes everything that follows.
Take an insurance contract. Is it enough to know that one policy covers the whole family for sports in general? Or do you want to store what it covers for each household member, under which conditions, with which contract number? There is no universal answer. There is only the question your future self, or your future agent, will actually ask.
The rule of thumb: store knowledge at the level of detail at which it will be retrieved and reused. A long contract is a poor unit if the question is "is our son's volleyball season covered?" Each box should hold one self-sufficient piece of knowledge: a unit of information that can be reused.
Once you have small, separate pieces, each one can carry a label. Metadata, simply put, is data about the data: what this piece is about, where it comes from, how it relates to other pieces. At a bare minimum, where it comes from. Other labels (topic, importance, people involved) can be suggested by a model, as long as someone reviews them.
A shelf this tidy still has a flaw. The sports insurance contract belongs in the Insurance box. It also belongs next to the volleyball club. An item can only sit in one cube.
You can solve this by leaving a note in the second cube: "see Insurance." A simple pointer teaching which box holds this data. Do that systematically and you no longer have a strict tree of boxes. You have a graph, where pieces are connected, pointing to each other.
A tree sorts knowledge along a single dimension (by topic, or by date, or by person) and can only imitate the rest with pointers. A graph builds the relationships in. Which one you need depends on whether your questions follow one dimension or cut across several.
What does a label look like in practice? It can be as simple as a YAML header: a few lines of plain text between two --- markers at the top of a file. No database, no special tool; any text file can carry one.
Here is the insurance contract from the shelf (illustrative; adapt the fields to the questions you actually ask):
---
title: Sports insurance, family policy
type: contract
topic: insurance
covers: [Lucy, Matt, son]
applies_to: sports practice, competition included
source: insurer's policy document (PDF), saved next to this file
related: [sports/volleyball-club, finance/bank-account]
---
The agent, or a small script, reads these headers to build the index (one list of every box and its labels). It can filter on topic: insurance or covers: son, and follow related to jump from the contract to the club, which is exactly the "see Insurance" note.
Start with the few fields you will really use.
(Later articles add the ones that matter once knowledge ages and has to be defended.)
Several knowledge units can then be assembled to bring the relevant context to the LLM.
What Lucy's agent actually did
Back to Saturday afternoon. Here is what happened behind Lucy's filled-in form.
The agent opened the box with the current status of the subscription, and the preferences (occasional play, not competition). It opened the contact book to retrieve the son's name, age and T-shirt size. It found the written medical approval. It pulled the insurance contract to confirm that a full season of practice is covered. It read the bank details needed for payment.
Five pieces of knowledge with nothing in common, assembled for a need that exists here and now. Notice what did not happen: nobody wrote a "volleyball registration" document in advance. Each piece was stored once, for its own reasons, in its own box.
The same medical approval that served today will serve next month's school trip.
It was the same agent and the same model as Matt's. It simply started from the right five boxes.
Yes, that agent just used a medical approval and bank account details from Lucy's local file system.
(Who may open which box is a question of its own, and it deserves its own article.)
Why picking beats stuffing
You might object that modern models can read very long documents, so why not hand over everything and let the model sort it out?
Because more is not better. The context window (the amount of text a model can consider at once) is limited, and LLM's attention inside it is not evenly spread. When the one exception that matters sits among a hundred irrelevant pages, models can fail to give it the weight it deserves. This is sometimes called prompt dilution: the signal is in the prompt, but buried under the amount of all information.
Selective retrieval (fetching only the stored pieces a task needs) works the other way round. The agent identifies what it needs, fetches those pieces, and builds a small, task-specific context.
How does it know which box? From an index: the labels of every box, collected in one list. The agent filters on the labels first (this person, this topic, this contract), and may then use similarity search (finding text that resembles the question) inside the few boxes that remain, filtering noise out.
None of these techniques is new. The discipline is:
Knowledge units and labels must be good enough for the index to work.
Guessing across a pile of documents is the failure; looking up in the index is the fix.
Two consequences follow. The agent can work against a knowledge base far larger than any context window. And the answer is easier to check, because you know which five boxes it opened.
It also explains why starting a fresh conversation and uploading a few files by hand is a weak long-term strategy for complex work. You are rebuilding the context from memory every time, starting from scratch: which sources matter, which versions are right, how they relate. The system depends on you reconstructing the shelf in your head.
On the other side, a library of self-contained knowledge units with proper metadata compounds over time.
A labeled shelf is not enough: agent still need steering
A well-labeled shelf tells the agent where things are. It does not tell it what they mean or what to do with them. Three layers of steering remove the guesswork.
The first is meaning. An ontology (a formal description of the kinds of concepts that exist in your domain and how they connect) and a semantic layer (a shared dictionary that gives each business term one agreed meaning across teams and systems) tell the agent what the labels stand for. If "customer" means a buyer for one team and a patient for another, the agent will happily mix them.
I covered both in The Garden Nobody Else Could Read.
The second is standing instructions: the system prompt and the skills (saved instructions for one recurring task, such as filling in a club registration, loaded only when that task comes up).
They tell the agent what this shelf is for, which boxes to open first and what never to touch. They are stored knowledge too, written once and read every time, not typed per request.
Think of it as a note taped to the side of the shelf.
The third is the request itself. With the first two in place, it can stay short. "Help me sign our son up for volleyball" was enough for Lucy.
Structure is necessary. Steering tells the agent how to use it.
You still need good instructions
Steering does not replace a clear goal, constraints and acceptance criteria in each request. But no prompt compensates for knowledge the system cannot find.
Engineer the context, not the prompt.
The same idea, at company scale
Now take the idea out of the household and into the kind of deliverable that organizations are actually afraid of.
A regulatory submission is the file a company sends to a health authority to obtain or keep approval for a medicine. It is assembled from many documents (quality, clinical, safety, labeling) written by different teams, and it follows an internationally harmonized structure, the Common Technical Document, usually submitted in its electronic form (eCTD).
Consider the regulatory affairs lead, on the week the dossier has to be submitted. Much of the effort is not writing. It is finding and reconciling: which component applies to this submission, where it lives, who holds the current one. Every missing piece means a message to another team and a wait.
Treat each of those components as a modular unit in its own labeled box, and the logic of the volleyball applies at scale. The agent retrieves the components this submission requires, identifies the applicable requirements, flags what is missing, and prepares the assembly.
It is a controlled assembly of existing, controlled and approved content. Not an attempt to generate a submission from a loosely worded prompt.
Cherry on top of the cake: you can trace each original component to every place it is used, across versions.
Crucially, this does not mean handing regulatory compliance to an LLM. The agent assists with retrieval and preparation. Deterministic processes (that apply explicit rules and always give the same output for the same input) check the structure and validate the format. People stay in the loop for every decision that needs judgment or a signature (Human-in-the-loop is the gate). Each part has a defined job.
That split matters beyond pharma. Some decisions can be delegated to a model. Others belong to explicit conditions, calculations and approval workflows.
The right architecture combines them instead of asking the model to improvise everything.
Swap in a bank's policy pack, an engineering team's release, or a procurement dossier, and the shape is the same: many small pieces, one deliverable, and the hard part is picking and assembling the right ones.
The honest cost
I would not believe anyone who says this is free.
Someone must decide what to keep, how to cut it into units, which labels matter and how the pieces relate. That is knowledge engineering, and it is real work, mostly at the start. It is often the hardest part of the whole initiative, and no model removes it.
You can automate part of it. A model can propose categories, extract dates, spot likely duplicates, suggest relationships. But a suggestion is not validated knowledge. Labels with consequences need explicit rules, reliable systems or human review; which ones, and who answers for them, is a story for later in this series.
And the rigor should match the risk. A personal assistant that helps you sign a child up for volleyball does not need the governance of a regulated submission. Over-engineering the first is as much a failure as under-engineering the second.
There is one more upside, often missed. A model upgrade lasts until the next release. A well-organized body of knowledge benefits every model, agent and workflow you connect to it, now and later.
What this means for you
Go back to Lucy and Matt. The price per token was identical. What differed was an up-front effort in organizing knowledge, from which every later task benefits.
Same tool. Same LLM. Same cost. Different usage.
If you keep three things from this article, keep these:
- Consolidating is not organizing. The problem is selection, not storage.
- Store knowledge at the level of detail at which it will be retrieved: small pieces, each with a label for where it comes from and how it relates to others.
- Engineer the context, not the prompt.
A first shelf is smaller than it sounds. Take the deliverable you assemble most often, and list the five or six pieces of knowledge it needs; that list is where to start.
For a technical team, plain files in a repository with an index file listing every file and its labels are enough. The novelty is not the storage. It is that each piece is a unit with labels, and the agent selects by them instead of reading everything.
One thing this first picture hides: everything on this shelf has a date on it, whether anyone wrote it down or not. A box that was right last spring may be quietly wrong today, and an agent that finds it will not notice. Whether a box is the right box is one question. Whether it is still true is another, and it is where the next article begins.
For now, one question to sit with:
if an AI agent had to produce your most important deliverable tomorrow, could it find, understand and assemble what it needs from your data?
Find more on the "Modular Knowledge" series
- Part 1/4 (this article): The differentiator is the knowledge, not the LLM
- Part 2/4: How to handle outdate content
- Part 3/4 (coming soon): Knowledge ownership & lifecycle
- Part 4/4 (coming soon): Your knowledge base is a data product
About the author
- Beyond 10 years in DevSecOps, cloud architecture and FinOps, I’m now focused on one question: How do we turn AI demos into reliable, secure and production-grade systems? I write about AI systems engineering, RAG architectures, agent security, LLM infrastructure, observability, evaluation pipelines and AI FinOps — through the lens of real-world engineering constraints: scale, cost, governance, reliability and operations. Because building with AI is easy. Operating it safely in production is the hard part.
Comments
Join the discussionNo comments yet. Be the first to comment.